Deep Representation Learning & Approximation Theory
Neural approximation theorems, optimization dynamics, and relational query engines
Pairs MIT 6.7960 Deep Learning (Isola & Beery) with CMU 15-799 Query Optimization (Pavlo) to contrast learned continuous representations with algebraic cost-based execution engines.
Curriculum sequence
5
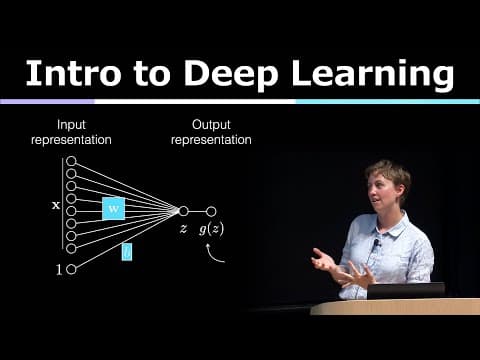
Lecture 01: Introduction to Deep Learning (6.7960)
Frames representation learning as hierarchical composition of parameterized differentiable transformations.
Lecture 02: How to Train a Neural Net (6.7960)
Analyzes stochastic gradient descent, loss landscapes, and adaptive preconditioning in deep networks.
Lecture 03: Approximation Theory (6.7960)
Proves universal approximation properties and contrasts width versus depth expressivity.

Lecture 1: SQL Optimization Background (15-799)
Establishes declarative query optimization as search over equivalent relational algebra plans.
Lecture 2: History of Query Optimizers ft. IBM System R (15-799)
Dissects IBM System R's bottom-up dynamic programming optimizer and Selinger selectivity estimation.