Opening Guest Lecture: Aviral Kumar (UC Berkeley CS 285)
Guest Lecture: Aviral Kumar (UC Berkeley CS 285)
- Length
- 56 min
- Level
- Graduate
- Recorded
- UC Berkeley2023
Opening Guest Lecture: Aviral Kumar (UC Berkeley CS 285)
Chapter 1 of 6: Before the lecture
Kumar traces offline Q-learning's failure to scale to an implicit regularizer and adds an explicit loss term.
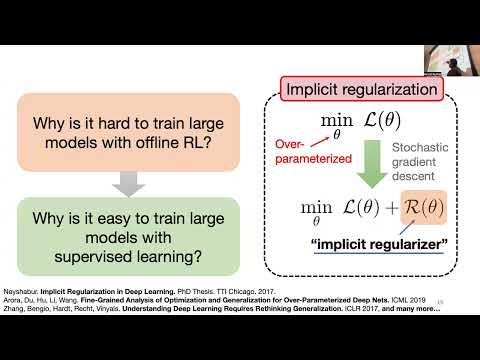
Offline reinforcement learning can pre-train large models for robotics and decision-making, yet naive Q-learning degrades as model capacity grows. Kumar, in a guest lecture for UC Berkeley CS 285, contrasts the implicit regularization of temporal-difference learning with that of supervised learning. He identifies a term in the RL regularizer that conflicts with feature norms and adds an explicit loss to undo it, restoring scaling. Further sections train value functions on human videos without action labels to obtain visual encoders for robot control. Cal-QL then calibrates Q-values against a reference function to prevent unlearning during online fine-tuning.
Offline reinforcement learning can pre-train large models for robotics and decision-making, yet naive Q-learning degrades as model capacity grows. Kumar, in a guest lecture for UC Berkeley CS 285, contrasts the implicit regularization of temporal-difference learning with that of supervised learning. He identifies a term in the RL regularizer that conflicts with feature norms and adds an explicit loss to undo it, restoring scaling. Further sections train value functions on human videos without action labels to obtain visual encoders for robot control. Cal-QL then calibrates Q-values against a reference function to prevent unlearning during online fine-tuning.
DR3: Value-Based RL Requires Explicit Regularization
Offline RL on Diverse Multi-Task Data Both Scales and Generalizes
Implicit Under-Parameterization Inhibits Data-Efficient Deep RL

This lecture
Lecture 72 of 73 of Deep Reinforcement Learning.
Choose a node to see how it connects to this lecture. What comes before is on the leftat the top. What comes after is on the rightat the bottom. The ring is what it teaches. People and places are above. Other lectures and books are below.
Press a chosen node again to open it.
Your comment is kept while you sign up.Sign in
A Simple Framework for Contrastive Learning of Visual Representations
Multi-Game Decision Transformers
Agent 57: Outperforming the Human Atari Benchmark
Implicit Regularization in Deep Learning
Fine-Grained Analysis of Optimization and Generalization for Over-Parameterized Deep Nets
Understanding Deep Learning Requires Rethinking Generalization
Implicit regularization in supervised learning
Implicit regularization in offline RL
Blanc et al. COLT 2021
Kumar et al. ICLR 2022
Kumar et al. ICLR 2023
Bhateja et al. 2023
Kumar et al. RSS 2023
Ebert, Yang et al. RSS 2022
Robotic Offline RL from Internet Videos via Value-Function Pre-Training
Reinforcement Learning from Passive Data via Latent Intentions
Learning One Representation to Optimize All Rewards
Cal-QL: Calibrated Offline RL Pre-Training for Efficient Online Fine-Tuning
Pre-Training for Robots: Offline RL Enables Learning New Tasks in a Handful of Trials
Robot Fine-Tuning Made Easy: Pre-Training Rewards and Policies for Autonomous Real-World RL
Supervised learning implicit regularization
Offline RL implicit regularization


