Lucas Beyer
Co-Creator of Vision Transformer · Stanford University · Distinguished
Lucas Beyer is a computer vision and deep learning researcher at Google Brain and OpenAI who co-created the Vision Transformer (ViT) and SigLIP.
- lectures
- 6
- series
- 1
- hours
- 6
Start here
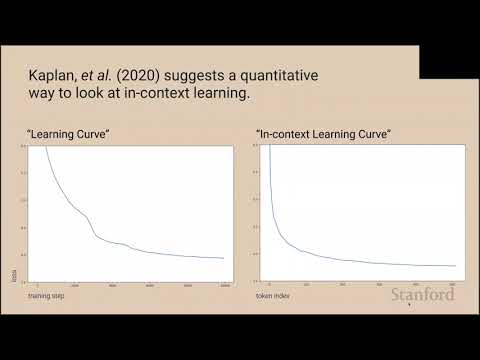
- Transformer Circuits, Induction Heads, In-Context Learningfrom Raschka, Build a Large Language Model (From Scratch)
- Decision Transformer: Reinforcement Learning via Sequence Modelingfrom Raschka, Build a Large Language Model (From Scratch)

- Self Attention and Non-parametric transformers (NPTs)from Raschka, Build a Large Language Model (From Scratch)
Series and courses
Stanford CS25: Transformers United
In these lectures
- Mechanistic interpretability aims to reverse engineer neural network weights into human-understandable computer programs.Transformer Circuits, Induction Heads, In-Context Learning
- Reinforcement learning can be framed as a sequence modeling problem to leverage the scalability and stability of Transformer architectures.Decision Transformer: Reinforcement Learning via Sequence Modeling
- Most supervised deep learning relies on parametric prediction where test-time outputs depend exclusively on learned parameters rather than the training data itself.Self Attention and Non-parametric transformers (NPTs)
Draws on
People cited in the lectures, at the moment of the citation.
- Catherine OlssonAnthropic colleague cited on the title slide.
- Nelson ElhageAnthropic colleague cited on the title slide.
- Chris OlahLecturer and Anthropic colleague cited on the title slide.
- Lukasz KaiserGoogle researcher cited as a colleague during Aidan Gomez's internship.
- Noam ShazeerGoogle researcher mentioned as working on autoregressive models.
- Jakob UszkoreitGoogle researcher mentioned as part of the transformer project.
Playlists
1


About
Lucas Beyer is a computer vision and deep learning researcher at Google Brain and OpenAI who co-created the Vision Transformer (ViT) and SigLIP. His Stanford CS25 lecture covers the VTAB benchmark, scaled supervised pre-training and ViT's patch embeddings, and assumes deep learning.
Taught with
Same subject, AI & Machine Learning
Connections
13Their places, courses, books and lectures.
Scholars2
Institutions2
Concept1
Lectures6
- Transformer Circuits, Induction Heads, In-Context Learning
- Decision Transformer: Reinforcement Learning via Sequence Modeling
- Self Attention and Non-parametric transformers (NPTs)
- Transformers United: DL Models that have revolutionized NLP, CV, RL
- Mixture of Experts (MoE) paradigm and the Switch Transformer
- Transformers in Vision: Tackling problems in Computer Vision