Opening Exploration of advanced topics in deep reinforcement learning
Exploration of advanced topics in deep reinforcement learning
- Length
- 11 min
- Level
- Undergraduate
- Recorded
- UC Berkeley2020
Opening Exploration of advanced topics in deep reinforcement learning
Chapter 1 of 3: Practical tips for Q-learning implementation
Practical implementations of deep Q-learning algorithms require careful debugging, hyperparameter tuning, and large replay buffers to achieve stable training across different environments. The lecture reviews optimization tips such as gradient clipping, Huber loss functions, double Q-learning, and multi-step returns to improve convergence and mitigate overestimation bias. Several historical and foundational papers are analyzed to demonstrate how these techniques apply to continuous control, robotic manipulation, and Atari game playing. Suggested readings and classic papers provide further context for advanced Q-learning architectures.
Your comment is kept while you sign up.Sign in
Reviews practical implementation tips for deep Q-learning and traces classic deep RL papers.
Practical implementations of deep Q-learning algorithms require careful debugging, hyperparameter tuning, and large replay buffers to achieve stable training across different environments. The lecture reviews optimization tips such as gradient clipping, Huber loss functions, double Q-learning, and multi-step returns to improve convergence and mitigate overestimation bias. Several historical and foundational papers are analyzed to demonstrate how these techniques apply to continuous control, robotic manipulation, and Atari game playing. Suggested readings and classic papers provide further context for advanced Q-learning architectures.
Prioritized experience replay
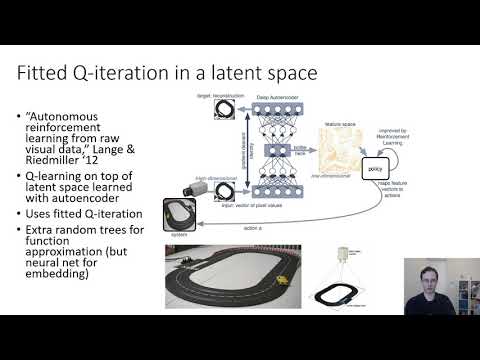
Autonomous reinforcement learning from raw visual data
Human-level control through deep reinforcement learning
Continuous control with deep reinforcement learning
Robotic manipulation with deep reinforcement learning and asynchronous off-policy updates
QT-Opt: Scalable Deep Reinforcement Learning of Vision-Based Robotic Manipulation Skills
Learning from delayed rewards
Neural fitted Q-iteration
This lecture
Lecture 24 of 73 of Deep Reinforcement Learning.
Choose a node to see how it connects to this lecture. What comes before is on the leftat the top. What comes after is on the rightat the bottom. The ring is what it teaches. People and places are above. Other lectures and books are below.
Press a chosen node again to open it.


