//
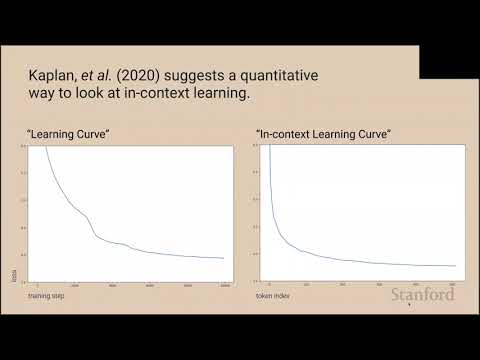
This lecture explores mechanistic interpretability in transformer language models, focusing on "induction head circuits." It elucidates how these attention head pairs enable in-context learning by allowing models to repeat or translate text, and mimic functions from prior examples.
"Neural network parameters can be thought of as compiled computer programs. Somehow, they encode sophisticated algorithms, capable of things no human knows how to write a computer program to do. Mechanistic interpretability seeks to reverse engineer neural networks into human understandable algorithms. Previous work has tended to focus on vision models; this talk will explore how we might reverse engineer transformer language models.
Co-Creator of the Transformer Architecture ('Attention Is All You Need')
Machine learning researcher and co-first author of 'Attention Is All You Need', introducing the self-attention Transformer architecture that underpins modern foundation models.
Co-Creator of Vision Transformer (ViT), Google Brain & OpenAI
Computer vision and deep learning researcher who co-created the Vision Transformer (ViT), SigLIP, and large-scale multimodal representation models.
Professor at Stanford University
William Fedus is a professor at Stanford University, specializing in machine learning and the development of transformer models and mixture of experts.