Introduction to Information Theory (University of Cambridge, Lecture 1)Mathematics·Standalone Lecture·Algorithmic Information & Coding Theory · David MacKay · University of CambridgeDavid MacKayUniversity of Cambridge—1:01:51
Reinventing Shannon Information Theory: Entropy & Optimal Prefix CodesMathematics·Standalone Lecture·Information Theory & Coding · Grant Sanderson · 3Blue1BrownGrant Sanderson3Blue1Brown7 ch32:19
Singular Value Decomposition (SVD): Mathematical OverviewMathematics·Standalone Lecture·Algorithmic Information & Coding Theory · Steve Brunton · University of WashingtonSteve BruntonUniversity of Washington3 ch12:50
Probability and CountingSTAT 110 · Probability · Lec 1·Combinatorics & Graph Theory · Joe Blitzstein · Harvard UniversityJoe BlitzsteinHarvard University—46:29
The unreasonable effectiveness of the convexity assumption in high dimensionsMathematics·Research Seminar·Convex Optimization · Bo'az Klartag · UC BerkeleyBo'az KlartagUC Berkeley—52:23
Community detection with the Bethe-HessianSystems & CS·Research Seminar·Probability & Information Theory · Yizhe Zhu · UC BerkeleyYizhe ZhuUC Berkeley—52:50
QED Lecture 1, Part 7: Summing Probability Amplitudes & Photomultiplier DetectionMathematics·Conference Talk·Formal Methods & Type Theory · Leni Aniva · Stanford UniversityLeni AnivaStanford University—21:06
Shannon's Channel and Capacity: A Mystery in Three ActsMathematics·Research Seminar·Topology & Geometry · Michelle Effros · CaltechMichelle EffrosCaltech—37:22
Information Theory: A Sample LectureMathematics·Standalone Lecture·Information Theory & Coding · Robert Harle · University of CambridgeRobert HarleUniversity of Cambridge—59:57
The Mathematics of Crime: Predictive Policing and Gang ActivityMathematics·Public Colloquium·Combinatorics & Graph Theory · Andrea L. Bertozzi · UCLAAndrea L. BertozziUCLA—1:12:49
Independence and ConditioningPrinciples of Discrete Applied Mathematics · Lec 2·Statistical Learning & Causality · Ankur Moitra · MITAnkur MoitraMIT—1:10:58
Dual Averaging Method for Regularized Stochastic Learning and Online OptimizationMathematics·Conference Talk·Systems Security · Lin Xiao · Google Research & TechTalksLin XiaoGoogle Research & TechTalks—24:39
Inclusion-ExclusionPrinciples of Discrete Applied Mathematics · Lec 3·Probability & Limit Theorems · Ankur Moitra · MITAnkur MoitraMIT—1:19:29
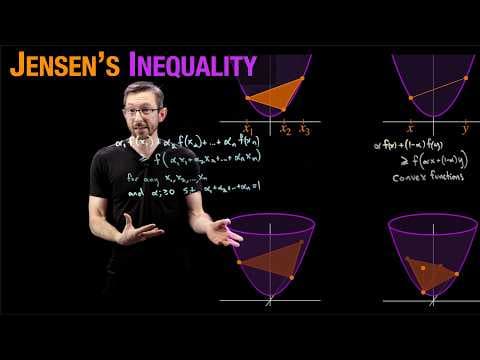
Jensen's Inequality: Intuition and ApplicationsOptimization Bootcamp: Convex Optimization for ML & Control · Lec 8·Probability & Limit Theorems · Steve Brunton · University of WashingtonSteve BruntonUniversity of Washington5 ch14:22
Story Proofs, Axioms of ProbabilitySTAT 110 · Probability · Lec 2·Combinatorics & Graph Theory · Joe Blitzstein · Harvard UniversityJoe BlitzsteinHarvard University—45:40
The Central Limit Theorem: Sums of Random Variables & ConvolutionsMathematics·Standalone Lecture·Probability & Limit Theorems · Grant Sanderson · 3Blue1BrownGrant Sanderson3Blue1Brown11 ch31:14
Error-Correcting Codes—Hamming CodesPrinciples of Discrete Applied Mathematics · Lec 19·Probability & Information Theory · Peter Shor · MITPeter ShorMIT—1:18:31
Data Compression and Shannon’s Noiseless Coding TheoremPrinciples of Discrete Applied Mathematics · Lec 16·Probability & Information Theory · Ankur Moitra · MITAnkur MoitraMIT—1:08:50
Tail BoundsPrinciples of Discrete Applied Mathematics · Lec 8·Probability & Limit Theorems · Ankur Moitra · MITAnkur MoitraMIT—1:20:53
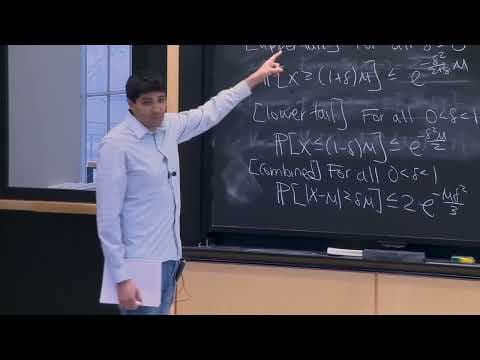
Chernoff BoundsPrinciples of Discrete Applied Mathematics · Lec 9·Probability & Limit Theorems · Ankur Moitra · MITAnkur MoitraMIT—55:18